
Here’s a statistic that should keep every engineering leader awake at night: test data management is consistently underestimated by 50 to 80 percent in automation budgets. Not the tooling. Not the infrastructure. The data itself, the synthetic users, the realistic transactions, the edge-case datasets that determine whether your AI testing agents actually validate anything meaningful or just burn compute cycles on glorified smoke tests.
We’ve spent years watching teams deploy sophisticated AI agents for web and mobile testing, only to watch those agents stumble on the same predictable obstacle: they don’t have the right data to do their jobs. And because test data management is rarely covered in vendor demos or conference talks, the problem stays invisible until it derails an entire release cycle.
Why Test Data for AI Testing Is Fundamentally Different
Traditional automation scripts are deterministic. You hardcode a username, a password, and a checkout flow. The script follows the path exactly as written. If the data changes, the script breaks, which is annoying, but at least the failure is obvious.
AI agents don’t work this way. They explore. They adapt. They make probabilistic decisions about what to test next based on what they observe. And that means test data for AI testing has to support exploration, not just execution.
A Web test AI agent that encounters the same five synthetic user accounts on every run will quickly exhaust meaningful paths. It needs variety. It needs realistic data distributions. It needs edge cases that mirror production without exposing production data. And most critically, it needs data that evolves as the application evolves, because an agent testing against stale data is an agent generating false confidence.
The old playbook, “let’s clone a subset of production and mask it”, doesn’t scale for AI-driven testing. AI agents consume data at volumes and velocities that make manual curation impossible. They need programmatic data generation, intelligent seeding, and automatic refresh cycles. And they need it without violating privacy regulations or creating security vulnerabilities.
The Four Dimensions of Test Data Management for AI Agents
If you’re building or deploying AI testing agents, your test data management strategy needs to account for four dimensions that traditional QA rarely considers.
1. Volume at Scale
A single AI agent might execute hundreds of exploratory paths in a single session. Each path may require unique accounts, transactions, documents, or configurations. Multiply that by parallel agents running across browsers, devices, and environments, and your data requirements explode.
Most teams discover this the hard way. They provision a few dozen test accounts and watch their AI agents hit duplicates, collisions, and state conflicts within the first hour of execution. The agents start failing not because the application is broken, but because the data has been exhausted.
The fix isn’t more manual data entry. Its automated data factories that generate realistic, varied datasets on demand, and clean them up after use so environments don’t accumulate toxic state.
2. Realism Without Exposure
AI agents are remarkably good at finding bugs that humans miss. But they’re also remarkably good at finding bugs that only exist because the test data was unrealistic.
If your synthetic orders always contain the same product combinations, your AI agent will never discover the inventory edge case that breaks checkout. If your test users all share the same demographic profile, your agent will miss the localization bug that affects a specific region. Realism matters.
At the same time, using production data for AI testing is a regulatory and security nightmare. GDPR, CCPA, HIPAA, and industry-specific frameworks create strict boundaries around how customer data can be used, and AI agents, by their nature, tend to expose data in unexpected ways during exploration.
The solution is intelligent synthetic data generation, systems that learn the statistical distribution and relational structure of production data without ever touching a real customer record. This isn’t simple masking or tokenization. It’s about building data that behaves like production data without being production data.
3. Cross-Platform Consistency
Here’s a scenario that plays out in engineering teams every week: an AI agent creates a user account through the web application, then attempts to complete a profile update through the mobile app. The web test passes. The mobile test fails. After four hours of debugging, the team discovers that the mobile API expects a slightly different date format than the web API, and the test data was generated to match the web format.
When Mobile AI agents span web and mobile interfaces, test data management becomes a cross-platform synchronization problem. The data that seeds a web session must be compatible with the data expectations of a mobile session. The state created by one agent must be readable by another.
This requires a unified data layer, a single source of truth for test data that all agents reference, regardless of which platform they’re testing. Without it, you’re not testing your application. You’re testing your ability to keep test datasets in sync.
4. Stateful Cleanup and Isolation
Traditional automation typically runs against isolated test environments where a little data pollution is manageable. AI agents, especially when running in parallel, create complex state webs that interfere with each other.
Agent A creates an order. Agent B cancels it. Agent C tries to fulfill it. If these operations happen in an unpredictable sequence, which they will, because AI agents explore non-deterministically, you get race conditions that have nothing to do with your application’s actual quality.
Effective test data management for AI agents requires not just generation but lifecycle management. Data must be created with expiration timestamps. Environments must be reset between runs. Agents must be able to request isolated data partitions when needed. And everything must happen automatically, because no human can orchestrate data cleanup for a hundred parallel exploratory sessions.
Why This Never Gets Budgeted
If test data is so critical, why is it consistently underfunded?
First, it doesn’t demo well. A vendor can show you an AI agent autonomously navigating an application, and it looks magical. Showing you a data pipeline that generates ten thousand realistic but synthetic user profiles? That’s infrastructure. It’s invisible work. It doesn’t make for compelling screenshots.
Second, the cost is deferred. Teams can get away with thin test data for the first few months of AI agent deployment. The agents find bugs, everyone celebrates, and the budget seems validated. It’s only when coverage needs to scale, when edge cases matter, when regulatory requirements tighten, that the data gap becomes catastrophic. By then, the tool is purchased, the team is trained, and the budget is spent.
Third, ownership is ambiguous. Is test data a QA responsibility? A DevOps concern? A data engineering problem? In most organizations, it falls through the cracks between teams, each assuming someone else is handling it.
The result is that test data management becomes the silent tax on every AI testing initiative. Teams spend 50 to 80 percent more than they budgeted, not on the agents themselves, but on the data infrastructure required to make those agents useful.
Building a Test Data Strategy That Scales
If you’re deploying or planning to deploy AI testing agents, here’s a practical framework for getting test data right before it becomes your biggest bottleneck.
Start With Data Requirements, Not Tool Requirements
Before evaluating AI testing platforms, document what your agents will need. How many unique user profiles per run? What transactional data must exist? What file uploads, API responses, and database states are prerequisites for meaningful exploration? This document becomes your data specification, and your reality check against vendor promises.
Invest in Programmatic Generation Early
Manual test data creation doesn’t scale. Period. Whether you use open-source libraries like Faker and TDK, commercial synthetic data platforms, or built-in generation capabilities from your testing vendor, commit to automation from day one. The investment pays back within the first quarter.
Treat Test Data as Production Infrastructure
Test data pipelines deserve the same rigor as production data pipelines. Version control your generation scripts. Monitor data quality metrics. Alert on generation failures. Apply the same security standards to test data storage that you apply to production databases, because attackers don’t distinguish between the two.
Measure Data Coverage, Not Just Code Coverage
Code coverage tells you what your agents touched. Data coverage tells you whether they touched it with meaningful inputs. Track metrics like unique data combinations exercised, edge-case ratios, and data freshness. If your agents keep testing the same scenarios because the data is repetitive, your coverage numbers are lying to you.
Plan for Regulatory Evolution
Privacy regulations are tightening globally. What’s acceptable today may not be acceptable next year. Build your test data management strategy with compliance in mind from the start, not as an afterthought. Synthetic data, differential privacy, and strict access controls aren’t optional features, they’re foundational requirements.
The Sofy.ai Perspective
At SOFY.AI, we’ve watched hundreds of teams deploy AI testing agents. The pattern is consistent: the teams that succeed aren’t necessarily the ones with the biggest budgets or the most sophisticated tooling. They’re the ones that treated test data as a first-class concern from day one.
Our platform is built on the understanding that AI agents are only as good as the data they consume. That’s why we’ve invested heavily in intelligent data orchestration, ensuring that every agent deployment is backed by realistic, varied, and automatically managed test datasets that scale with your application’s complexity.
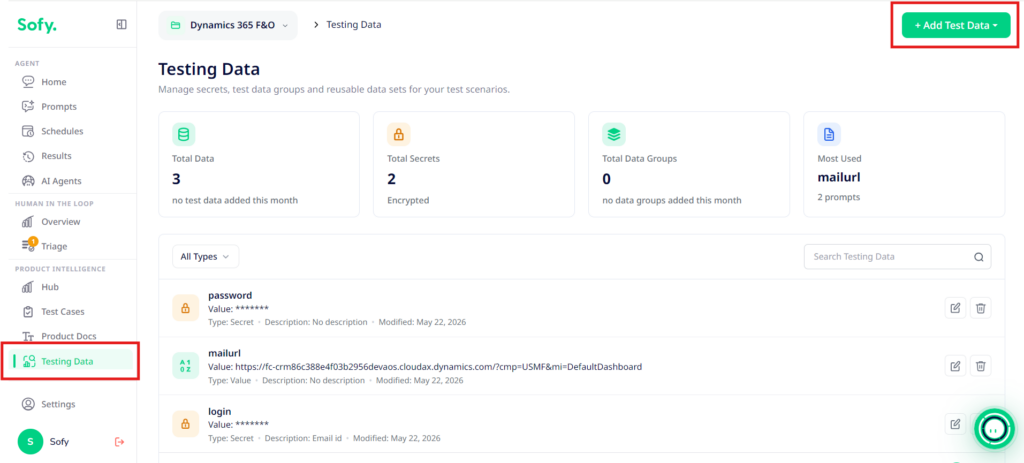
Because the truth is, you can buy the most advanced AI testing agents on the market. But if you feed them thin, repetitive, or unrealistic data, you’re not testing your application. You’re just running an expensive randomizer.
The conversation around AI testing has been dominated by agents, models, and autonomous exploration. Those are important. But they’re only half the equation. The other half, the half that determines whether your AI initiative succeeds or becomes another line item in the post-mortem, is test data management.
If you’re budgeting for AI testing, allocate for data. If you’re evaluating vendors, ask about data. If you’re planning your roadmap, prioritize data infrastructure alongside agent capabilities.
The teams that get this right will ship faster, catch more meaningful bugs, and avoid the hidden costs that derail so many automation programs. The teams that don’t will discover, too late, that their agents were never the problem. The data was., at production data volume, across every surface, so that logic nobody documented still has to produce the right result.
Stop Feeding Your AI Agents Junk Data
You’ve invested in intelligent testing agents. Don’t let bad test data silently sabotage them. SOFY.AI builds realistic, self-managing test datasets directly into every agent deployment, so your automation actually finds the bugs that matter, not the ones your data invented.