
Every testing maturity model written before 2024 measures roughly the same thing: how much of your testing runs without a person doing it. Levels go up as coverage goes up. It was a reasonable proxy for two decades, because the only way to raise coverage was to build capability, so the number moved with the maturity underneath it.
That proxy has broken. A team can now generate several hundred tests in an afternoon, and the honest question, are any of them checking the right thing, and would you notice if they stopped?, is not answered anywhere on a coverage chart. Meanwhile the thing being tested has changed shape. When the system under test is an AI agent that can reach a correct outcome by three different routes, a percentage has nothing to attach itself to.
So this is a maturity model built on a different axis. Agentic testing maturity is not how much you have automated. It is how large a decision you can let an agent make unattended, and how confident you are that you would find out if it went wrong.
Below: five levels, the five dimensions that make most organizations uneven across them, a fifteen-question self-assessment you can run in a team meeting, and an honest section on what maturity models of this kind get wrong, including this one.
Why Coverage Stopped Being a Maturity Signal
Take two organizations. Both report 80% regression coverage.
The first generated most of that suite last quarter with an AI assistant. The tests assert that screens loaded and success messages appeared. Every failure goes into a queue that one engineer works through on Friday afternoons, and the ones that look flaky get re-run until they pass. Nobody has opened the coverage report since the number hit 80.
The second has 80% too, but the suite asserts business outcomes at the data layer, failures arrive pre-diagnosed, and last month an agent stopped a run and escalated because a vendor’s embedded AI agent had started approving invoices it previously routed for review. Somebody read that escalation the same day.
Same number. Not remotely the same organization. Whatever we are measuring when we say “maturity,” it is clearly not in that percentage, which is why an AI testing maturity model has to measure something else.
The Axis That Matters: Delegated Trust
Two things have to move together for maturity to be real.
Scope of unattended decision, how big a judgement you are willing to let an agent make with nobody watching. Choosing which of two selectors to use is small. Deciding a release is safe to ship is large.
Confidence of detection, how sure you are that if the agent got it wrong, you would find out, and soon enough to matter.
Maturity is not how much you have stopped doing by hand. It is how much you have stopped watching, and been right to.
Move one without the other and you get a recognizable failure mode. Wide delegation with weak detection is not maturity, it is exposure that has not surfaced yet. Strong detection with no delegation is not maturity either, it is a very well-instrumented manual process. The levels below are defined by where an organization sits on both at once.
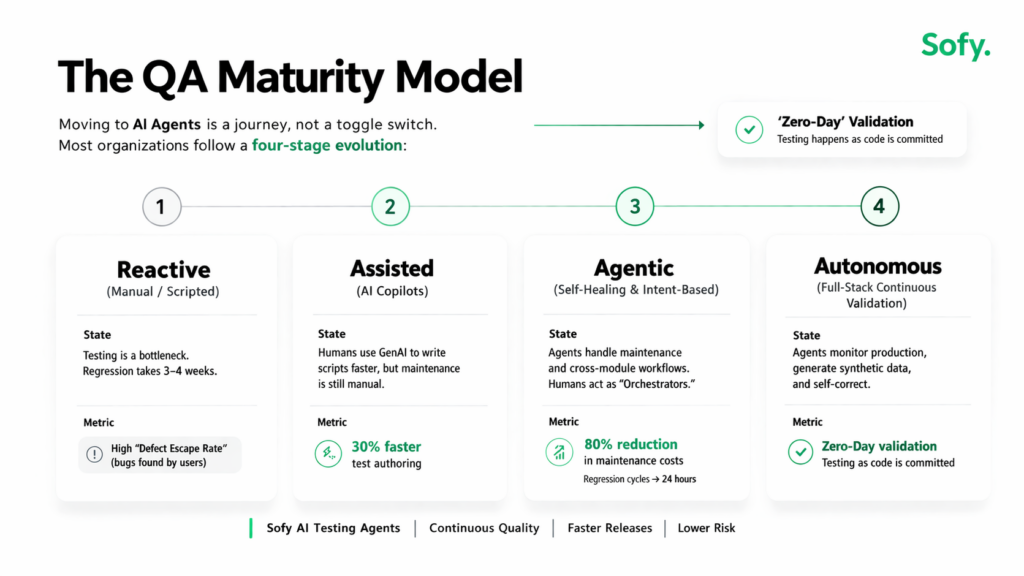
The Five Levels
Each level is described by what is observably true, not by what a team intends. Intentions are not maturity.
| LEVEL 0 | Assisted, Agents suggest. Humans do. |
AI drafts test cases; a person reviews, adjusts and runs them. The generation is genuinely faster, and the output is genuinely useful, but nothing executes without a human in the path. Most organizations currently describing themselves as “doing AI testing” are here, and there is no shame in it, it is the correct first step.
Observable indicator: if every AI feature you use were switched off tomorrow, your release process would be slower but structurally unchanged.
What it costs: nothing yet. The constraint is still authoring capacity, which is what the tooling is addressing.
The move up: let something run on a schedule without being asked to.
| LEVEL 1 | Supervised Execution, Agents run. Humans read everything. |
Tests execute on a schedule. Results land in a dashboard. A person still reads every failure and decides what it means. This is where the most common and most expensive plateau in the industry sits, and it gets its own section below because almost nobody recognizes it while they are in it.
Observable indicator: test creation time has dropped sharply and release cadence has not changed at all.
What it costs: the constraint moved from authoring to triage, and triage does not scale with headcount the way authoring did. Generating more tests now makes things worse.
The move up: make failures self-explaining, then define one scope that runs unattended.
| LEVEL 2 | Delegated Coverage, A defined scope runs with nobody watching. |
Some meaningful slice of testing, a module, a regression pack, a nightly suite, runs unattended, with written guardrails on what the agent may do and a named escalation path where humans still belong in agentic testing. Crucially, the scope is written down. An undocumented delegation is not a delegation; it is an assumption.
Observable indicator: a run completed last week that nobody opened the results of, and that was the right call.
What it costs: governance work most teams underestimate, defining scope, agreeing escalation, deciding who owns the answer when an agent is wrong.
The move up: stop repairing the suite after every release.
| LEVEL 3 | Self-Maintaining, Coverage survives change without human repair. |
The application changes and the suite does not need editing, not because selectors were patched (self healing test automation), but because the tests were never expressed as routes in the first place. Test data provisions itself. Drift is detected and reported rather than discovered by someone wondering why a number looks odd.
Observable indicator: the last release changed the interface and nobody touched a test.
What it costs: it requires intent-based authoring end to end. Organizations that reach Level 3 in one area and stay at Level 1 elsewhere usually did so because half the suite is still recorded.
The move up: point the same discipline at systems that do not behave deterministically.
| LEVEL 4 | Governed Autonomy, Agents validate agents, and you can prove it. |
The subject of testing now includes non-deterministic systems, the AI agents embedded in your ERP, your service desk, your finance close. Validation covers the decision itself rather than the output of a fixed path, escalation runs on policy rather than on someone noticing, and the evidence of what was validated exists in a form an auditor accepts without three days of assembly.
Observable indicator: you have at least one test that passes or fails on an agent’s judgement, and you can produce its evidence trail in minutes.
What it costs: real governance maturity, not just tooling. This is the level most organizations will not reach in 2026, and for many of them that is the correct outcome.
The Level 1 Plateau, and Why Almost Nobody Sees It
The largest cluster of organizations sits at Level 1, and the reason is mechanical rather than cultural.
Automation historically had one bottleneck: writing tests. Every tool, every budget request and every maturity model of the last fifteen years was aimed at it. Then generation got genuinely cheap, that bottleneck dissolved, and the constraint moved one step downstream, to reading results, without anybody re-measuring.
So the team now produces four times the tests and ships at the same cadence, because the same two people still triage every failure. Worse, the classic response makes it worse: generate more coverage, produce more failures, and lengthen the queue. The dashboard fills up with runs nobody opens, and “flaky” quietly becomes the label for any failure too expensive to investigate.
The tell is simple. If test creation time fell by 70% and release cadence did not move, the constraint is not where you are spending.
Getting off the plateau is not a tooling purchase, though tooling is part of it. It is two moves in order. First, make failures self-explaining, test failure root cause analysis that arrives with its cause attached takes a minute instead of forty, which is what actually restores triage capacity. Second, pick one scope, write down what the agent may and may not do inside it, and stop reading those results.
The second move is harder than the first, and it is not a technical problem. Somebody has to be willing to not look.
Five Dimensions: Nobody Is One Level
Organizations are almost never at a single level. It is entirely normal to be at Level 3 in maintenance and Level 0 in governance, because tooling raised one dimension while practice never moved on another.
| Dimension | L0 Assisted | L1 Supervised | L2 Delegated | L3 Self-Maintaining | L4 Governed |
| Authoring | Humans write; AI suggests | AI drafts; humans approve | Non-coders author intent | Intent survives change | Agents propose coverage gaps |
| Execution & triage | Manual runs | Scheduled; every result read | Unattended within a scope | Failures self-explain | Escalation by policy |
| Maintenance | Rewrite from scratch | Repair each release | Selectors heal | Route re-derived; no repair | Drift detected proactively |
| Governance & evidence | None | Run logs only | Scope + guardrails written | Evidence retained per run | Audit-ready without assembly |
| Subject under test | UI flows | UI plus some API | Data layer | Integrations and document chains | Non-deterministic agents |
One rule for reading the grid, and it is the part that gets argued about: your real level is your lowest dimension, not your average.
Averaging feels fairer and is wrong, because these dimensions do not compensate for one another. Self-maintaining coverage with no governance does not give you governed autonomy at a discount, it gives you a suite that adapts smoothly to change while nobody can say what it validated when the auditor asks. The weakest dimension is where the failure comes from, so it is the one that sets your position.
The Self-Assessment: Fifteen Things That Are Either True or Not
Maturity questionnaires usually fail because they ask about intentions, do you have a documented strategy for X, and every organization says yes. These fifteen are observable. Somebody in the room either knows a specific instance or does not.
Tick only what is true right now, not what is planned. Three statements per dimension.
Authoring
☐ Someone who does not write code created a test that is still running unchanged three months later.
☐ You can read one of your tests and say what it establishes without opening the application.
☐ Nobody on the team maintains a locator or selector library.
Execution & triage
☐ A run finished last week that nobody opened the results of, and that was the right decision.
☐ When a test fails, the report tells you why, not just that it did.
☐ Failures are routed by cause rather than read top to bottom by one person.
Maintenance
☐ The last release changed the interface and nobody edited a test.
☐ You can name the last time the suite needed repairing, and it was more than a month ago.
☐ Test data for a run is provisioned without anyone raising a ticket.
Governance & evidence
☐ You could show an auditor what was validated, when, and what the system returned, without assembling it by hand.
☐ An agent escalated to a human in the last month, and you can say what it escalated and why.
☐ There is a written answer to “what is this agent not allowed to do,” and a test that checks it.
Subject under test
☐ You validate at the data layer, not at the success message.
☐ At least one test passes or fails on an AI agent’s decision rather than a deterministic output.
☐ You would detect a behaviour change in a vendor’s embedded agent within one release cycle.
Scoring
| Ticks in a dimension | That dimension sits at | What it means |
| 0 | Level 0, Assisted | Humans still in every path. Correct starting position. |
| 1 | Level 1, Supervised | Running unattended is the next move. Check the plateau section. |
| 2 | Level 2, Delegated | Real delegation exists. Durability is the constraint. |
| 3 | Level 3+, Self-maintaining or beyond | Ahead of most. Governance is usually the lagging dimension. |
HOW TO READ YOUR SCORE Score each dimension separately, do not total the fifteen. Your organization’s agentic testing maturity is the lowest of the five, and the gap between your highest and lowest dimension is more useful than either number on its own. A spread of three or more levels almost always means tooling has outrun practice, and the next investment should be practice.
Three Things Maturity Models Get Wrong, Including This One
Level 4 is not the goal
Maturity models imply that the top is where everyone should be heading, and for most organizations that is false. The right target level is set by blast radius, not ambition. A team shipping a marketing site does not need governed autonomy and should not spend on it. A team whose agents post journal entries in a public company has no choice. Decide your target level deliberately, then stop, over-governing low-stakes testing is a real and common waste.
You cannot buy a level
Tooling sets your ceiling. Practice sets your floor. Buying a platform capable of Level 3 while operating at Level 1 discipline produces Level 1 outcomes and a larger invoice, which is a pattern visible in a great many disappointed automation programs. The dimensions that move with a purchase are authoring and maintenance. Execution, governance and subject move only when someone changes how the organization works.
Levels are not skipped, though they can be short
Every organization that has reached delegated coverage went through a period of supervised execution first, because the trust required is built by watching something behave correctly for a while and then choosing to stop watching. That period can be weeks rather than years, and good tooling shortens it considerably. It cannot be deleted.
Where Sofy Sits in the Model
Sofy AI Testing agents is built for the two transitions where organizations most often stall, Level 1 to 2, and Level 2 to 3, and provides the validation layer that Level 4 requires.
Level 1 → 2: removing the triage tax. Sofy’s ERP testing agents express tests as business outcomes, so a failure arrives stating what should have been true and what was true instead. That is the difference between a forty-minute investigation and a one-minute read, and restoring triage capacity is the precondition for letting anything run unattended.
Level 2 → 3: coverage that survives change. Because no route is stored, an interface change does not put the suite into rework. The agent derives the path again on the next run. This is the dimension most teams believe they have bought and most have not, which the assessment tends to expose.
Supporting Level 4: validating non-deterministic systems. For organizations whose ERP now contains vendor AI agents, Sofy validates the decision rather than the path, retains the evidence of what was checked, and surfaces behavioral drift agent observability as it appears rather than after it has been noticed downstream.
What Sofy does not do is supply the other half. Writing down what an agent may and may not do, agreeing who owns the answer when it is wrong, and deciding to stop reading a dashboard are organizational acts. Tooling can make them safe. It cannot make them for you, and an honest maturity model should say so. Also check out our blog “What Are AI Agents for ERP Testing? A Smarter Approach to Quality Assurance“.
Frequently Asked Questions
What is agentic testing maturity?
It is a measure of how much testing judgement an organization can delegate to AI agents without supervision, paired with how reliably it would detect a wrong judgement. It deliberately replaces automation coverage as the maturity axis, because coverage now says more about generation speed than about capability, two organizations with identical coverage can be four levels apart.
How is this different from TMMi or a traditional test automation maturity model?
Traditional models measure process discipline and automation percentage, both of which assume a human decides what each test means. An AI testing maturity model has to measure delegation and detection instead, and has to account for a subject under test that may not behave deterministically, neither of which older models were built to describe. They are complements rather than replacements; TMMi still describes process maturity well.
What level are most organizations at in 2026?
Level 1, supervised execution, by a wide margin, usually without knowing it. The diagnostic is whether test creation time has fallen sharply while release cadence has not moved. If both are true, authoring was solved and triage was not.
Can we reach Level 3 without changing tools?
Only if your existing tests express intent rather than routes, which is uncommon in recorded or script-based suites. Level 3 means the application can change without anyone editing a test, and that is an architectural property of how tests are stored, not a discipline you can apply to a suite built on selectors. This is usually the transition that requires a platform decision, and it is the one Sofy is built for.
Does every organization need to reach Level 4?
No, and pursuing it indiscriminately wastes money. Target level should follow blast radius. If your agents make decisions with financial, regulatory or safety consequences, posting to a ledger, approving a payment, releasing a shipment, Level 4 is not optional. If they do not, Level 2 or 3 is a perfectly rational place to stop.
How often should we re-run the assessment?
Once a quarter is enough, and the useful output is not the score but the movement and the spread. A dimension that has not moved in three quarters is either deliberately parked or quietly blocked, and knowing which is the point of running it again.
The Bottom Line
The industry spent fifteen years optimizing the wrong constraint, and got very good at it. Authoring is close to solved. What has not moved at the same speed is the organizational capacity to let something run without watching it, which is now the thing that actually separates teams.
That is why the useful question is no longer how much of your testing is automated. It is which decisions you have handed over, whether you wrote down the limits, and whether you would find out in time if an agent got one wrong.
Run the fifteen statements with your team. The number matters less than the argument you will have about statement four, the run nobody opened, and whether that was the right decision. Teams that can answer it comfortably are further along than their coverage chart suggests. Teams that go quiet have just found their next quarter’s work.